Animating Frescoes
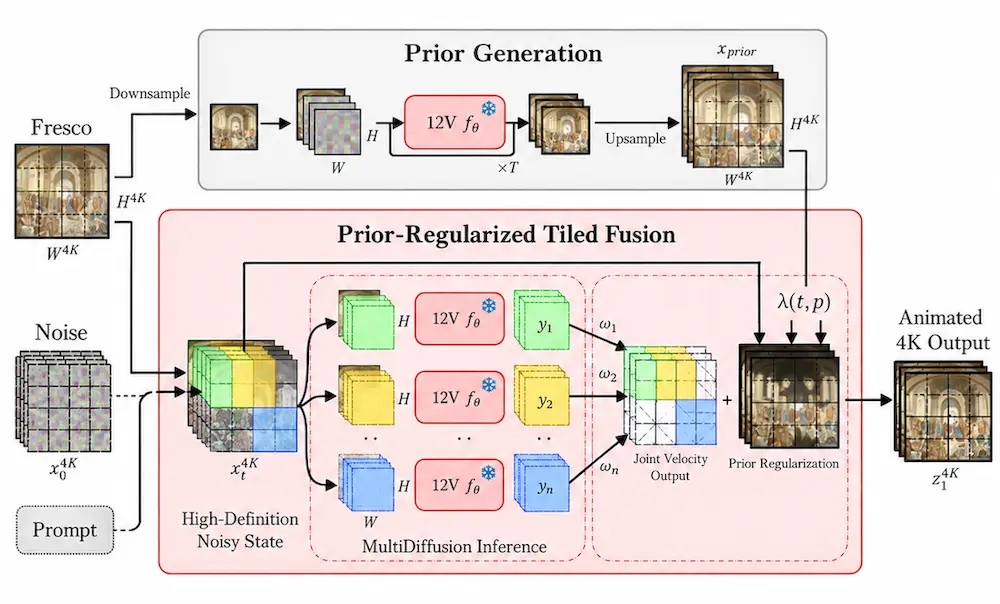
FrescoDiffusion turns a single ultra-high-resolution image into video at the same scale, preserving fine details that standard image-to-video models lose when complex scenes are resized.
Instead of generating one low-resolution clip and simply upscaling it, the method performs tiled diffusion directly on a large latent canvas.
A Global Prior for Local Detail
A low-resolution animation first captures the global structure and motion of the image. Its latent trajectory is then upscaled and used as a prior to guide every step of the 4K tiled denoising process.
This prior regularization keeps separate tiles coherent while still allowing the model to create new details and motion at full resolution.
Controlling What Moves
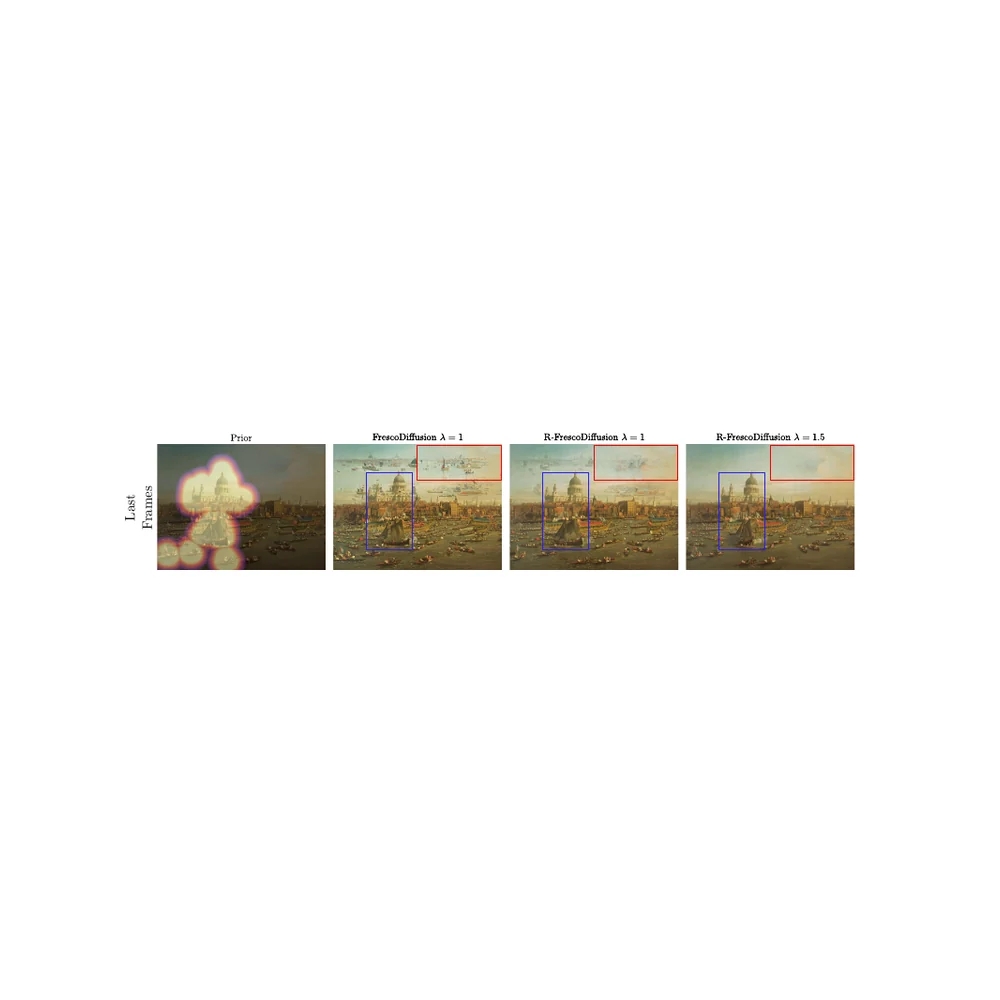
FrescoDiffusion can treat different regions independently, relaxing the prior earlier on active areas while keeping backgrounds constrained for longer. This creates motion without breaking the overall composition.
Tests on FrescoArchive and VBench-I2V show improved coherence, fidelity and controllability over tiled baselines, with only a small runtime overhead.